Ketamine PK and MADRS, blood pressure and heart rate PD in treatment-refractory depression (Abuhelwa 2022)
Source:vignettes/articles/Abuhelwa_2022_ketamine.Rmd
Abuhelwa_2022_ketamine.RmdModel and source
Abuhelwa et al. (2022) built population PK/PD models of racemic ketamine in adults with treatment-refractory depression who received single ketamine doses of 0.1-0.5 mg/kg by i.v., s.c. or i.m. injection. A joint ketamine + norketamine PK model was developed first and then held fixed while three separate PD models were fitted (sequential PPP&D approach): an indirect-response turnover model for the Montgomery-Asberg Depression Rating Scale (MADRS) total score, and immediate-effect Emax models for mean arterial blood pressure and for heart rate. The four models are packaged as four files that share this article.
model_names <- c(
  pk = "Abuhelwa_2022_ketamine",
  madrs = "Abuhelwa_2022_ketamine_madrs",
  map = "Abuhelwa_2022_ketamine_map",
  hr = "Abuhelwa_2022_ketamine_hr"
)
mods <- lapply(model_names, function(nm) rxode2::rxode(readModelDb(nm)))
#> ℹ parameter labels from comments will be replaced by 'label()'
#> ℹ parameter labels from comments will be replaced by 'label()'
#> ℹ parameter labels from comments will be replaced by 'label()'
#> ℹ parameter labels from comments will be replaced by 'label()'- Citation: Abuhelwa AY, Somogyi AA, Loo CK, Glue P, Barratt DT, Foster DJR. Population Pharmacokinetics and Pharmacodynamics of the Therapeutic and Adverse Effects of Ketamine in Patients With Treatment-Refractory Depression. Clin Pharmacol Ther. 2022;112(3):720-729. doi:10.1002/cpt.2640.
- PK model: Joint parent-metabolite population PK model of racemic ketamine and norketamine after i.v., s.c. and i.m. ketamine in adults with treatment-refractory depression (Abuhelwa 2022). Ketamine has two-compartment disposition with first-order absorption shared by the s.c. and i.m. routes (common ka and common absolute bioavailability of 64.4 percent); all ketamine clearance forms norketamine (fraction metabolised assumed 1, so the norketamine clearances and volumes are apparent values divided by fm), which has its own two-compartment disposition. All clearances and volumes are scaled allometrically to 70 kg (exponent 0.75 for clearances, 1 for volumes). Residual error is proportional for ketamine (additive term fixed near zero) and combined additive plus proportional for norketamine.
- MADRS model: Population PK/PD model for the antidepressant effect of racemic ketamine on the Montgomery-Asberg Depression Rating Scale (MADRS) total score in adults with treatment-refractory depression (Abuhelwa 2022). The MADRS score is a turnover state (baseline 22.3, turnover time 1/kout = 42.1 h) whose zero-order production is inhibited by plasma ketamine through an Emax model with Emax fixed to 1 and EC50 0.439 ng/mL; norketamine has no effect. Ketamine and norketamine PK (two-compartment each, first-order s.c./i.m. absorption with a common ka and 64.4 percent bioavailability, all ketamine clearance forming norketamine, allometric scaling to 70 kg) are the final PK model of Abuhelwa_2022_ketamine, held fixed.
- Blood-pressure model: Population PK/PD model for the acute effect of racemic ketamine on mean arterial blood pressure (MAP) in adults with treatment-refractory depression (Abuhelwa 2022). MAP is an immediate (no-delay) additive sigmoid Emax function of plasma ketamine: baseline 97.1 mmHg, Emax 51.6 mmHg, EC50 468 ng/mL, Hill 2.04; norketamine has no effect. Ketamine and norketamine PK (two-compartment each, first-order s.c./i.m. absorption with a common ka and 64.4 percent bioavailability, all ketamine clearance forming norketamine, allometric scaling to 70 kg) are the final PK model of Abuhelwa_2022_ketamine, held fixed.
- Heart-rate model: Population PK/PD model for the acute effect of racemic ketamine on heart rate (HR) in adults with treatment-refractory depression (Abuhelwa 2022). HR is an immediate (no-delay) Emax function of plasma ketamine rising from a baseline of 72.7 beats/min towards a maximum attainable HR fixed to 220 beats/min, with EC50 7580 ng/mL; between-subject variability is on the baseline and on EC50 (Table 3 and Results; the supplementary control stream instead places the second eta on the maximum attainable HR); norketamine has no effect. Ketamine and norketamine PK (two-compartment each, first-order s.c./i.m. absorption with a common ka and 64.4 percent bioavailability, all ketamine clearance forming norketamine, allometric scaling to 70 kg) are the final PK model of Abuhelwa_2022_ketamine, held fixed.
- Article: https://doi.org/10.1002/cpt.2640 (open access, PMC9540482). The supporting information holds the NONMEM control streams of the three PD models (Supplement S1), Tables S1-S3 and Figures S1-S7.
Population
Twenty-one adults with treatment-refractory depression (7 female, 14 male; mean age 49.5 years, range 29-69) contributed 61 ketamine treatment sessions from a double-blind, multiple-crossover dose-titration study (Loo 2016, including the Lai 2014 i.v. pilot). Ketamine 0.1-0.5 mg/kg was given as a single dose by i.v., s.c. or i.m. injection, with doses at least one week apart. CYP2B6 genotypes were *6/*6 (2), *1/*6 or *5 (8) and *1/*1 (11) (Table 1). Body weight was the only covariate retained (allometric scaling to 70 kg); its distribution is not reported. Sex and CYP2B6 genotype were tested and not retained.
str(mods$pk$population)
#> List of 13
#>  $ species       : chr "human"
#>  $ n_subjects    : int 21
#>  $ n_studies     : int 2
#>  $ age_range     : chr "29-69 years"
#>  $ age_median    : chr "50 years (mean 49.5)"
#>  $ weight_range  : chr "not reported"
#>  $ sex_female_pct: num 33.3
#>  $ disease_state : chr "Treatment-refractory major depression (MADRS >= 20 before each treatment)"
#>  $ dose_range    : chr "Racemic ketamine 0.1-0.5 mg/kg single doses in a within-subject dose-titration design, by i.v., s.c. or i.m. in"| __truncated__
#>  $ regions       : chr "Australia (University of New South Wales, Sydney)"
#>  $ genotype      : chr "CYP2B6 *6/*6 : *1/*6 or *5 : *1/*1 = 2 : 8 : 11"
#>  $ n_observations: chr "278 ketamine and 278 norketamine plasma concentrations (Table S1); 14 percent of concentrations were below the "| __truncated__
#>  $ notes         : chr "Demographics from Abuhelwa 2022 Table 1 (7 female, 14 male). Data are from 61 ketamine treatment sessions of th"| __truncated__
Source trace
Every ini() value carries an in-file comment pointing to
its source. The PD files repeat the PK block with every PK parameter
fixed, as in the supplementary PD control streams.
| Quantity | Value | Source |
|---|---|---|
lka (s.c. and i.m.) |
log(6.53 1/h) | Table 2 ‘KA ketamine’; one $THETA for both routes |
lfdepot (s.c. and i.m.) |
log(0.644) | Table 2 ‘F extravascular’; F2 = F3 in Supplement S1 |
lcl, lvc, lq,
lvp
|
log(69.6 L/h), log(79.3 L), log(121 L/h), log(87.4 L) | Table 2 ketamine rows |
lcl_nk, lvc_nk, lq_nk,
lvp_nk
|
log(30.3 L/h), log(73.6 L), log(54.2 L/h), log(339 L) | Table 2 norketamine/fm rows |
| Allometric exponents | 0.75 (clearances), 1 (volumes), reference 70 kg | Methods ‘General modeling approach’; Supplement S1 $PK |
etalcl, etalvc, etalvp,
etalcl_nk, etalvc_nk
|
0.0341, 0.219, 0.182, 0.424, 0.217 | Supplement S1 $OMEGA; Table 2 BSV 18.5, 46.8, 42.7, 65.1, 46.6 %CV |
propSd, addSd (ketamine) |
0.294, 0.00001 ng/mL (fixed) | Table 2 RUVPROP / RUVADD ketamine |
propSd_nk, addSd_nk
|
0.257, 3.88 ng/mL | Table 2 RUVPROP / RUVADD norketamine |
lrbase_madrs |
log(22.3) | Table 3 MADRS BASE |
lec50_madrs |
log(0.439 ng/mL) | Table 3 MADRS EC50 |
limax_madrs, lhill_madrs
|
log(1), log(1) (fixed) | Table 3 MADRS Emax 1 Fix, HILL 1 Fix |
lkout_madrs |
log(1/42.1 1/h) | Table 3 MADRS TURN = 42.1 h; KOUT = 1/TURN in Supplement S1 |
etalrbase_madrs, etalkout_madrs
|
0.0767, 0.841 | Table 3 PPV_BASE 27.7 %CV, PPV_TURN 91.7 %CV |
addSd_madrs, propSd_madrs
|
5.15, 0.0001 (fixed) | Table 3 MADRS RUV_ADDPD, RUV_PROPPD |
lrbase_map, lemax_map,
lec50_map, lhill_map
|
log(97.1 mmHg), log(51.6 mmHg), log(468 ng/mL), log(2.04) | Table 3 BP column |
etalrbase_map, etalec50_map
|
0.0106, 0.36 | Table 3 BP PPV_BASE 10.3 %CV, PPV_EC50 60.0 %CV |
addSd_map, propSd_map
|
6.98 mmHg, 0.0001 (fixed) | Table 3 BP RUV_ADDPD, RUV_PROPPD |
lrbase_hr, lec50_hr
|
log(72.7 beats/min), log(7580 ng/mL) | Table 3 HR column |
lrmax_hr, lhill_hr
|
log(220 beats/min), log(1) (fixed) | Table 3 HR Emax 220 Fix, HILL 1 Fix; Results |
etalrbase_hr, etalec50_hr
|
0.0231, 2.43 | Table 3 HR PPV_BASE 15.2 %CV, PPV_EC50 156 %CV |
addSd_hr, propSd_hr
|
9.15 beats/min, 0.0001 (fixed) | Table 3 HR RUV_ADDPD, RUV_PROPPD |
| PK ODEs (two-compartment ketamine, all CL forming norketamine, two-compartment norketamine) | n/a | Figure 1; Supplement S1 $DES |
MADRS turnover:
d/dt(madrs) = kin * (1 - Imax * C / (EC50 + C)) - kout * madrs,
madrs(0) = BASE
|
n/a | Methods equations; Supplement S1 $DES
(DADT(7)=KIN-KOUT*A(7), A_0(7)=EBASE) |
MAP: BASE + Emax * C^h / (EC50^h + C^h)
|
n/a | Figure 1; Supplement S1 BP $ERROR |
HR: BASE + (Emax - BASE) * C / (EC50 + C)
|
n/a | Supplement S1 HR $ERROR |
Residual error sqrt((prop * IPRED)^2 + add^2)
|
n/a | Supplement S1 $ERROR |
The between-subject variabilities are reported as %CV and converted with omega^2 = (CV/100)^2. That is the convention of this paper: the PK $OMEGA values in Supplement S1 are exactly the squares of the Table 2 %CVs (sqrt(0.0341) = 0.185 for the 18.5 %CV on ketamine clearance).
Ketamine and norketamine PK by route
The study sampled plasma up to 4 h after each dose (Figure 2). The simulation below gives 0.5 mg/kg to a 70 kg virtual patient by each route: i.v. as the 40-min infusion used in the paper’s dosing simulations, s.c. and i.m. as injections into the shared absorption depot.
wt_ref <- 70
dose_ug <- function(mg_per_kg, wt = wt_ref) mg_per_kg * wt * 1000

# One event table per route; `id_offset` keeps subject IDs disjoint across
# routes so bind_rows() does not merge subjects.
make_route <- function(route, n, id_offset, mg_per_kg = 0.5, times = c(seq(0, 4, by = 1 / 12), 6, 8, 12, 24, 36, 48, 72)) {
  ids <- id_offset + seq_len(n)
  amt <- dose_ug(mg_per_kg)
  dose <- data.frame(
    id = ids, time = 0, amt = amt,
    rate = if (route == "i.v.") amt / (40 / 60) else 0,
    evid = 1L, cmt = if (route == "i.v.") "central" else "depot", dvid = NA_integer_
  )
  obs <- expand.grid(id = ids, time = times)
  obs$amt <- NA_real_
  obs$rate <- NA_real_
  obs$evid <- 0L
  obs$cmt <- "central"
  obs$dvid <- 1L
  out <- dplyr::bind_rows(dose, obs) |>
    dplyr::arrange(id, time, dplyr::desc(evid))
  out$WT <- wt_ref
  out$admin <- route
  out
}

n_route <- 200L
ev_pk <- dplyr::bind_rows(
  make_route("i.v.", n_route, 0L),
  make_route("s.c.", n_route, n_route),
  make_route("i.m.", n_route, 2L * n_route)
)
stopifnot(!anyDuplicated(unique(ev_pk[, c("id", "time", "evid")])))
rxode2::rxSetSeed(20220920)
sim_pk <- rxode2::rxSolve(
  mods$pk, events = ev_pk, keep = "admin", useLinCmt = FALSE,
  returnType = "data.frame"
)
stopifnot(!anyNA(sim_pk$Cc), !anyNA(sim_pk$Cc_nk))
sim_pk |>
  dplyr::filter(time <= 4) |>
  tidyr::pivot_longer(c(Cc, Cc_nk), names_to = "analyte", values_to = "conc") |>
  dplyr::mutate(analyte = ifelse(analyte == "Cc", "Ketamine", "Norketamine")) |>
  dplyr::group_by(admin, analyte, time) |>
  dplyr::summarise(
    q05 = quantile(conc, 0.05), q50 = median(conc), q95 = quantile(conc, 0.95),
    .groups = "drop"
  ) |>
  ggplot(aes(time, q50, colour = admin, fill = admin)) +
  geom_ribbon(aes(ymin = q05, ymax = q95), alpha = 0.15, colour = NA) +
  geom_line() +
  facet_wrap(~analyte, scales = "free_y") +
  labs(x = "Time after dose (h)", y = "Plasma concentration (ng/mL)", colour = "Route", fill = "Route")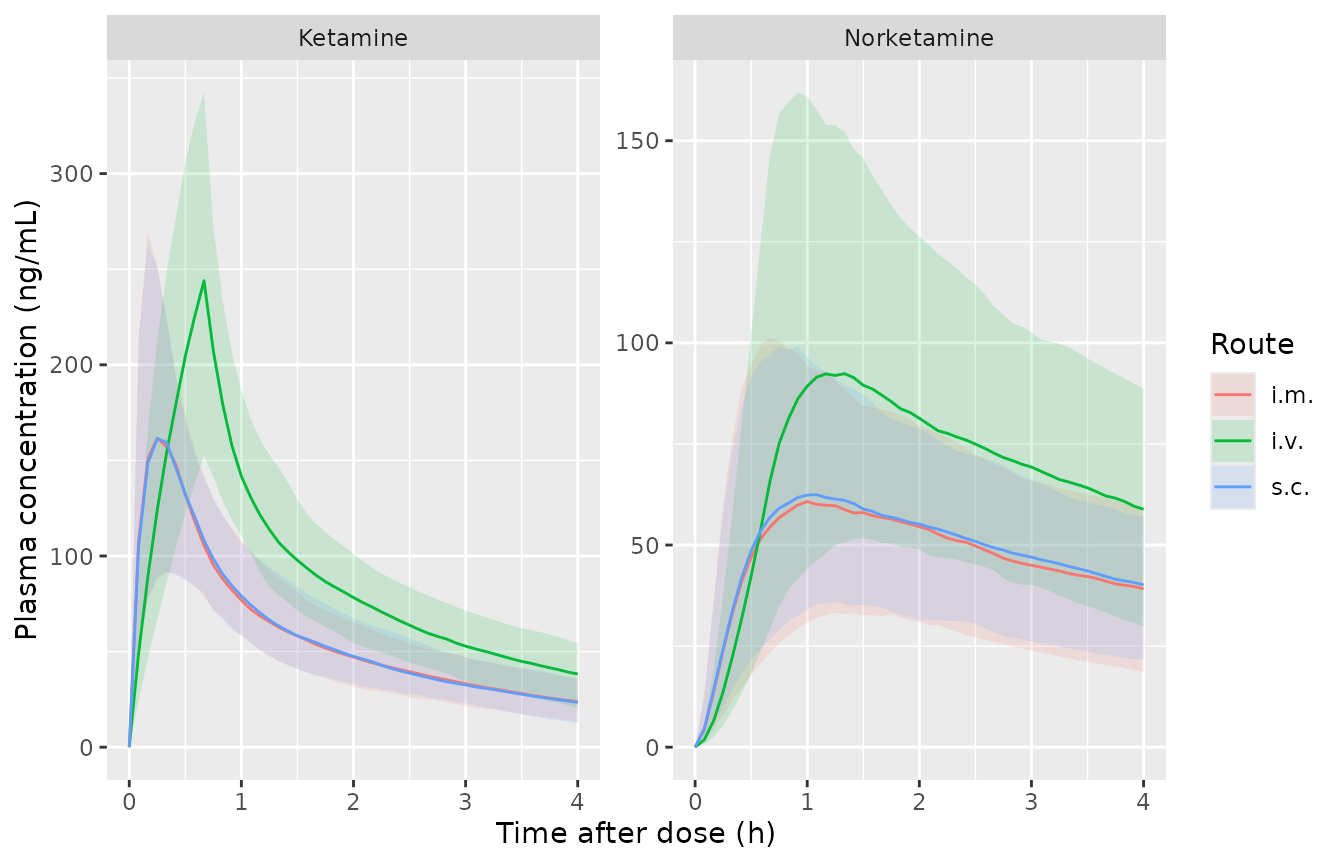
Ketamine and norketamine after 0.5 mg/kg by route: simulated median and 5th-95th percentiles over 0-4 h, the window of Figure 2 of Abuhelwa 2022 (which shows prediction-corrected VPCs pooled over routes and doses).
The s.c. and i.m. curves coincide because the final model shares one absorption rate constant (absorption half-life 6.4 min, quoted as 6.4 min in the Results) and one bioavailability between the two routes. Norketamine peaks about 0.5-1 h after the dose, matching the observed median in Figure 2b.
PKNCA validation
pk_nca_conc <- sim_pk |>
  dplyr::filter(!is.na(Cc)) |>
  dplyr::select(id, time, Cc, admin)
pk_nca_dose <- ev_pk |>
  dplyr::filter(evid == 1L) |>
  dplyr::select(id, time, amt, admin)

conc_obj <- PKNCA::PKNCAconc(pk_nca_conc, Cc ~ time | admin + id)
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
dose_obj <- PKNCA::PKNCAdose(pk_nca_dose, amt ~ time | admin + id)
intervals <- data.frame(
  start = 0, end = Inf,
  cmax = TRUE, tmax = TRUE, aucinf.obs = TRUE, half.life = TRUE
)
nca_res <- PKNCA::pk.nca(PKNCA::PKNCAdata(conc_obj, dose_obj, intervals = intervals))
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
nca_summary <- summary(nca_res)
knitr::kable(nca_summary, caption = "Simulated ketamine NCA after 0.5 mg/kg (70 kg) by route; geometric means with geometric CV.")| start | end | admin | N | cmax | tmax | half.life | aucinf.obs |
|---|---|---|---|---|---|---|---|
| 0 | Inf | i.m. | 200 | 158 [34.1] | 0.250 [0.0833, 0.417] | 2.21 [0.750] | 323 [17.1], n=186 |
| 0 | Inf | i.v. | 200 | 237 [26.0] | 0.667 [0.667, 0.667] | 2.25 [0.889] | 503 [16.8], n=181 |
| 0 | Inf | s.c. | 200 | 163 [32.3] | 0.250 [0.167, 0.417] | 2.19 [0.833] | 328 [16.6], n=184 |
The paper reports one ketamine Cmax, the model prediction for 0.5 mg/kg infused i.v. over 40 min in the dosing-regimen simulations (230 ng/mL; Singh 2016 observed 219 +/- 34 and 189 +/- 74 ng/mL).
published <- tibble::tribble(
  ~admin, ~cmax,
  "i.v.", 230
)
cmp <- nlmixr2lib::ncaComparisonTable(
  simulated = nca_res |> as.data.frame() |> dplyr::filter(admin == "i.v."),
  reference = published,
  by = "admin",
  units = c(cmax = "ng/mL"),
  tolerance_pct = 20
)
knitr::kable(cmp, caption = "Simulated vs. published ketamine Cmax, 0.5 mg/kg i.v. over 40 min. * differs from the reference by >20%.")| NCA parameter | admin | Reference | Simulated | % diff |
|---|---|---|---|---|
| Cmax (ng/mL) | i.v. | 230 | 244 | +6.1% |
Two deterministic checks on the PK structure: the typical-value AUC ratio between the extravascular and i.v. routes must equal the shared bioavailability of 0.644, and the typical-value Cmax at the end of the 40-min infusion is set against the paper’s 230 ng/mL.
ev_typ <- dplyr::bind_rows(
  make_route("i.v.", 1L, 0L, times = c(seq(0, 48, by = 1 / 60), seq(49, 240, by = 1))),
  make_route("s.c.", 1L, 1L, times = c(seq(0, 48, by = 1 / 60), seq(49, 240, by = 1)))
)
sim_typ <- rxode2::rxSolve(
  mods$pk, events = ev_typ, keep = "admin", omega = NA, sigma = NA,
  useLinCmt = FALSE, rtol = 1e-10, atol = 1e-12, returnType = "data.frame"
)
auc_typ <- sim_typ |>
  dplyr::group_by(admin) |>
  dplyr::summarise(
    auc = sum(diff(time) * (head(Cc, -1) + tail(Cc, -1)) / 2),
    cmax = max(Cc),
    .groups = "drop"
  )
auc_ratio <- auc_typ$auc[auc_typ$admin == "s.c."] / auc_typ$auc[auc_typ$admin == "i.v."]
cmax_iv_typ <- auc_typ$cmax[auc_typ$admin == "i.v."]
knitr::kable(auc_typ, digits = 2, caption = "Typical-value ketamine AUC(0-240 h) and Cmax, 0.5 mg/kg, 70 kg.")| admin | auc | cmax |
|---|---|---|
| i.v. | 502.87 | 246.83 |
| s.c. | 323.81 | 163.60 |
stopifnot(
  # Shared extravascular F = 0.644 (Table 2). The ratio is a property of the
  # structure, so only integration and trapezoid error separate it from F.
  abs(auc_ratio / 0.644 - 1) < 0.01,
  # Paper: model-predicted Cmax 230 ng/mL; a wrong volume or dose unit moves
  # this by tens of percent.
  abs(cmax_iv_typ / 230 - 1) < 0.15
)
The s.c./i.v. typical-value AUC ratio is 0.6439 and the typical i.v. Cmax is 247 ng/mL, 7.3% above the paper’s 230 ng/mL. The paper does not state the simulation time grid or the weights of its virtual Singh 2016 cohort; a grid that does not land exactly on the end of the infusion reads the peak slightly low.
Dosing-regimen simulations (Figures S6 and S7)
The paper simulated 0.5 mg/kg i.v. over 40 min given twice weekly (days 1, 4, 8, 11, 15, 18, 22 and 25) or three times weekly (days 1, 3, 5, 8, 10, 12, 15, 17, 19, 22, 24 and 26), the regimens of Singh 2016, and summarised MADRS, blood pressure and heart rate. Each PD model is solved on the same virtual cohort (200 per regimen, 70 kg). The paper’s simulated 90% bands for MADRS at baseline (about 15-35) match the between-subject variability alone, so the summaries below use the individual predictions without residual error.
regimens <- list(
  "Twice weekly" = c(1, 4, 8, 11, 15, 18, 22, 25),
  "Three times weekly" = c(1, 3, 5, 8, 10, 12, 15, 17, 19, 22, 24, 26)
)

make_regimen <- function(regimen, days, n, id_offset, obs_cmt, obs_dvid) {
  ids <- id_offset + seq_len(n)
  amt <- dose_ug(0.5)
  dose <- expand.grid(id = ids, time = (days - 1) * 24)
  dose$amt <- amt
  dose$rate <- amt / (40 / 60)
  dose$evid <- 1L
  dose$cmt <- "central"
  dose$dvid <- NA_integer_
  # Hourly grid plus the end of each infusion and the early post-dose BP/HR
  # sampling times (5, 10, 30 min).
  times <- sort(unique(c(
    seq(0, 28 * 24, by = 1),
    as.vector(outer((days - 1) * 24, c(1 / 12, 1 / 6, 0.5, 40 / 60), `+`))
  )))
  obs <- expand.grid(id = ids, time = times)
  obs$amt <- NA_real_
  obs$rate <- NA_real_
  obs$evid <- 0L
  obs$cmt <- obs_cmt
  obs$dvid <- obs_dvid
  out <- dplyr::bind_rows(dose, obs) |>
    dplyr::arrange(id, time, dplyr::desc(evid))
  out$WT <- wt_ref
  out$regimen <- regimen
  out
}

n_reg <- 200L
build_regimens <- function(obs_cmt, obs_dvid) {
  dplyr::bind_rows(
    make_regimen("Twice weekly", regimens[[1]], n_reg, 0L, obs_cmt, obs_dvid),
    make_regimen("Three times weekly", regimens[[2]], n_reg, n_reg, obs_cmt, obs_dvid)
  )
}
# MADRS is itself a state, so observation rows sit on it; MAP and HR are
# algebraic outputs, so observation rows sit on central with dvid = 1.
ev_reg_madrs <- build_regimens("madrs", NA_integer_)
ev_reg_alg <- build_regimens("central", 1L)
stopifnot(!anyDuplicated(unique(ev_reg_madrs[, c("id", "time", "evid")])))
rxode2::rxSetSeed(20220921)
sim_madrs <- rxode2::rxSolve(mods$madrs, events = ev_reg_madrs, keep = "regimen", useLinCmt = FALSE, returnType = "data.frame")
sim_map <- rxode2::rxSolve(mods$map, events = ev_reg_alg, keep = "regimen", useLinCmt = FALSE, returnType = "data.frame")
sim_hr <- rxode2::rxSolve(mods$hr, events = ev_reg_alg, keep = "regimen", useLinCmt = FALSE, returnType = "data.frame")
stopifnot(!anyNA(sim_madrs$madrs), !anyNA(sim_map$map), !anyNA(sim_hr$hr))

reg_long <- dplyr::bind_rows(
  sim_madrs |> dplyr::transmute(id, time, regimen, panel = "Ketamine (ng/mL)", value = Cc),
  sim_madrs |> dplyr::transmute(id, time, regimen, panel = "MADRS score", value = madrs),
  sim_map |> dplyr::transmute(id, time, regimen, panel = "MAP (mmHg)", value = map),
  sim_hr |> dplyr::transmute(id, time, regimen, panel = "HR (beats/min)", value = hr)
)
reg_summary <- reg_long |>
  dplyr::group_by(regimen, panel, time) |>
  dplyr::summarise(q05 = quantile(value, 0.05), q50 = median(value), q95 = quantile(value, 0.95), .groups = "drop") |>
  dplyr::mutate(
    panel = factor(panel, levels = c("Ketamine (ng/mL)", "MADRS score", "MAP (mmHg)", "HR (beats/min)")),
    regimen = factor(regimen, levels = names(regimens))
  )
reg_summary |>
  ggplot(aes(time / 24 + 1, q50)) +
  geom_ribbon(aes(ymin = q05, ymax = q95), fill = "slateblue", alpha = 0.25) +
  geom_line() +
  facet_grid(panel ~ regimen, scales = "free_y") +
  labs(x = "Day", y = NULL)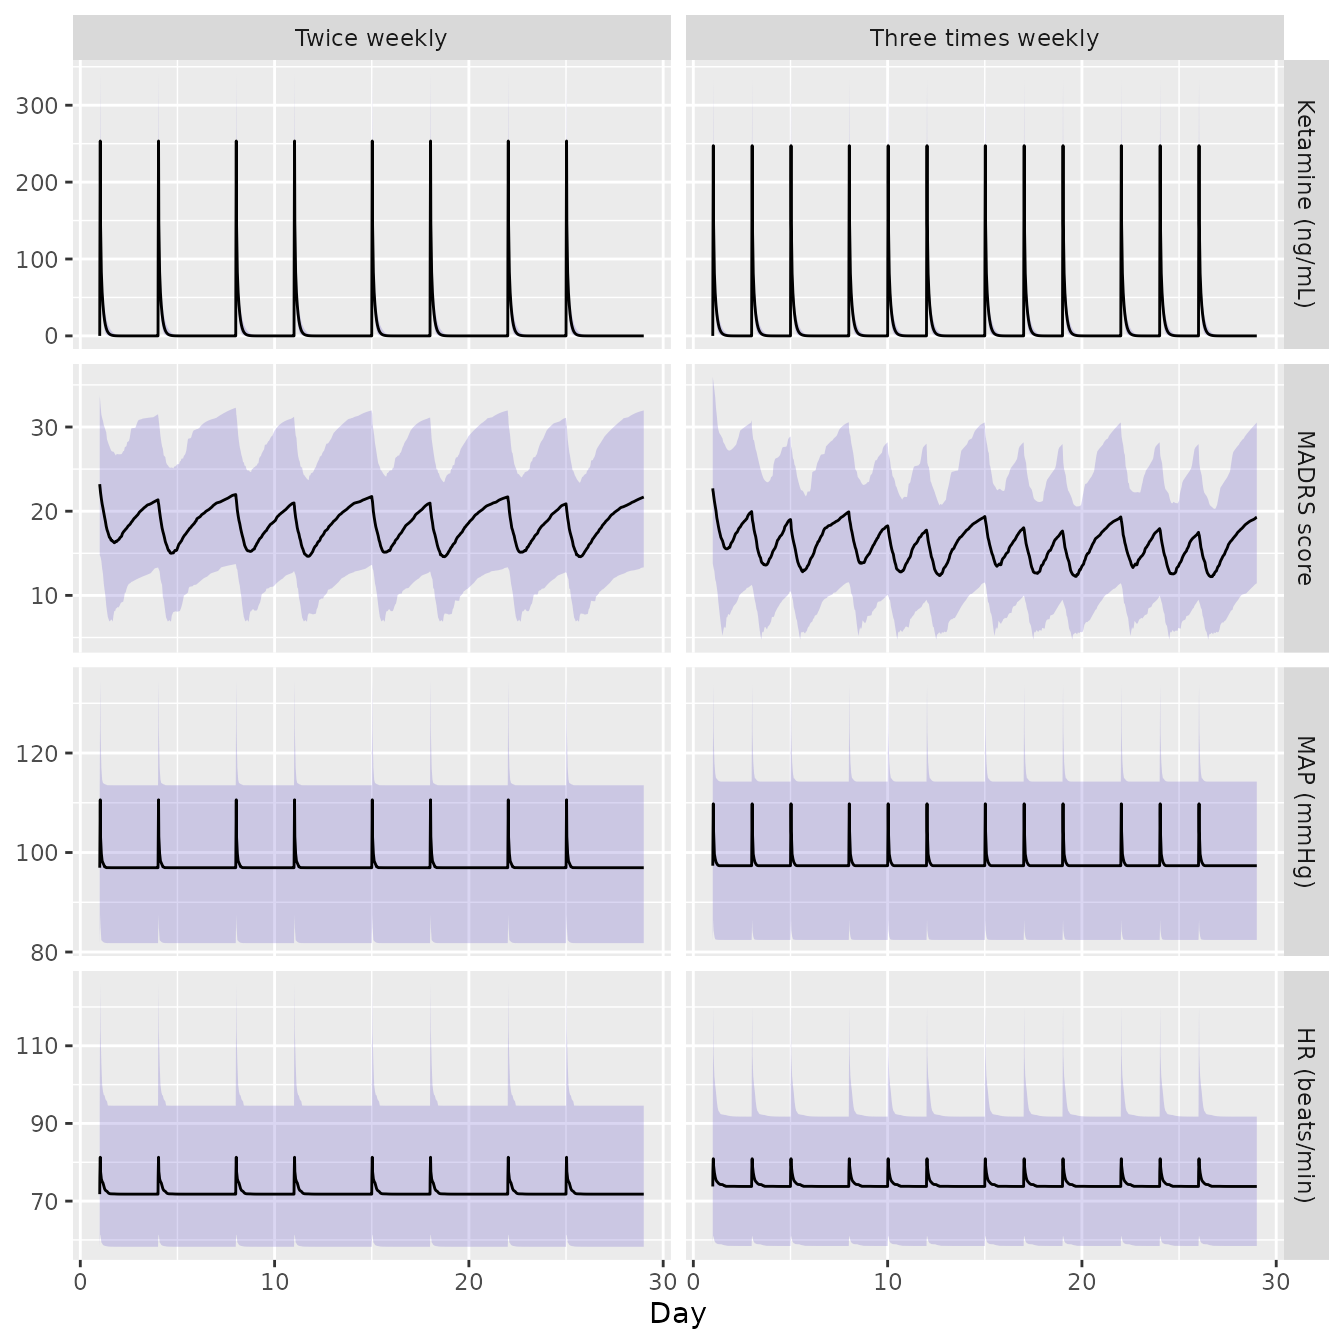
Median and 90% interval of ketamine concentration, MADRS, mean arterial pressure and heart rate for 0.5 mg/kg i.v. over 40 min twice or three times weekly. Replicates the top panels of Figures S6 and S7 of Abuhelwa 2022 (x axis in study days, day 1 = first dose).
madrs_ind <- sim_madrs |>
  dplyr::group_by(id) |>
  dplyr::mutate(base = madrs[time == 0]) |>
  dplyr::ungroup() |>
  dplyr::mutate(
    responder = 100 * (base - madrs) / base >= 50,
    remission = madrs <= 10
  )
madrs_pct <- madrs_ind |>
  dplyr::group_by(regimen, time) |>
  dplyr::summarise(
    `Response (>= 50% reduction)` = 100 * mean(responder),
    `Remission (MADRS <= 10)` = 100 * mean(remission),
    .groups = "drop"
  ) |>
  tidyr::pivot_longer(-c(regimen, time), names_to = "target", values_to = "pct")
madrs_pct |>
  ggplot(aes(time / 24 + 1, pct, colour = regimen)) +
  geom_line() +
  facet_wrap(~target) +
  labs(x = "Day", y = "Virtual patients (%)", colour = NULL) +
  theme(legend.position = "bottom")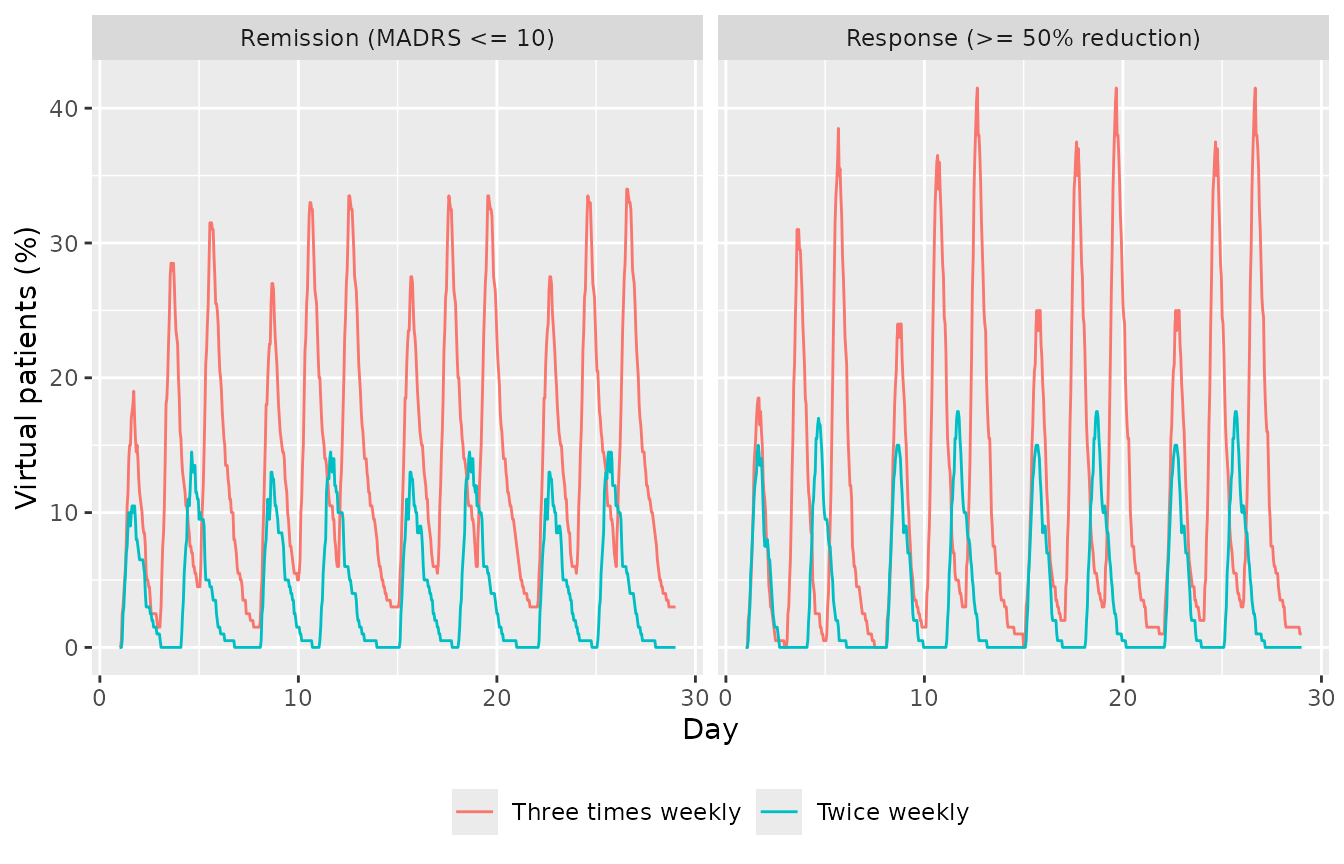
Percentage of virtual patients meeting the MADRS response and remission targets over time. Replicates the middle panels of Figures S6 and S7 of Abuhelwa 2022.
The Results report, for day 15, the percentage of responders and remitters (twice weekly 16.5% and 18%; three times weekly 25% and 26%). In Figures S6 and S7 these are the heights of the peaks that follow the day-15 dose, so they are compared with the maximum over the 48 h after that dose. The maximum percentage increases in heart rate and blood pressure from baseline (“<= 6.5% and 10%”) are compared with the median over patients of each patient’s maximum increase.
day15 <- 14 * 24
peak_after_day15 <- madrs_pct |>
  dplyr::filter(time >= day15, time <= day15 + 48) |>
  dplyr::group_by(regimen, target) |>
  dplyr::summarise(sim = max(pct), .groups = "drop")
pct_change_day15 <- madrs_ind |>
  dplyr::filter(time == day15) |>
  dplyr::group_by(regimen) |>
  dplyr::summarise(sim = median(100 * (base - madrs) / base), .groups = "drop") |>
  dplyr::mutate(target = "Median % decrease in MADRS, day 15 pre-dose")
max_pct <- function(df, var) {
  df |>
    dplyr::group_by(regimen, id) |>
    dplyr::summarise(pct = 100 * (max(.data[[var]]) - .data[[var]][time == 0]) / .data[[var]][time == 0], .groups = "drop") |>
    dplyr::group_by(regimen) |>
    dplyr::summarise(sim = median(pct), .groups = "drop")
}
regimen_cmp <- dplyr::bind_rows(
  peak_after_day15,
  pct_change_day15,
  max_pct(sim_map, "map") |> dplyr::mutate(target = "Median maximum % increase in MAP"),
  max_pct(sim_hr, "hr") |> dplyr::mutate(target = "Median maximum % increase in HR")
) |>
  dplyr::left_join(
    tibble::tribble(
      ~regimen, ~target, ~paper,
      "Twice weekly", "Response (>= 50% reduction)", 16.5,
      "Three times weekly", "Response (>= 50% reduction)", 25,
      "Twice weekly", "Remission (MADRS <= 10)", 18,
      "Three times weekly", "Remission (MADRS <= 10)", 26,
      "Twice weekly", "Median % decrease in MADRS, day 15 pre-dose", 11.5,
      "Three times weekly", "Median % decrease in MADRS, day 15 pre-dose", 18.3,
      "Twice weekly", "Median maximum % increase in MAP", 10,
      "Three times weekly", "Median maximum % increase in MAP", 10,
      "Twice weekly", "Median maximum % increase in HR", 6.5,
      "Three times weekly", "Median maximum % increase in HR", 6.5
    ),
    by = c("regimen", "target")
  )
regimen_cmp |>
  dplyr::select(target, regimen, paper, sim) |>
  dplyr::arrange(target, regimen) |>
  dplyr::rename("Quantity" = target, "Regimen" = regimen, "Paper" = paper, "Simulated" = sim) |>
knitr::kable(digits = 1, caption = "Day-15 efficacy and maximum cardiovascular effects: Abuhelwa 2022 Results (MAP and HR given as upper bounds) vs. this simulation.")| Quantity | Regimen | Paper | Simulated |
|---|---|---|---|
| Median % decrease in MADRS, day 15 pre-dose | Three times weekly | 18.3 | 12.5 |
| Median % decrease in MADRS, day 15 pre-dose | Twice weekly | 11.5 | 7.5 |
| Median maximum % increase in HR | Three times weekly | 6.5 | 5.2 |
| Median maximum % increase in HR | Twice weekly | 6.5 | 6.9 |
| Median maximum % increase in MAP | Three times weekly | 10.0 | 9.1 |
| Median maximum % increase in MAP | Twice weekly | 10.0 | 11.5 |
| Remission (MADRS <= 10) | Three times weekly | 26.0 | 27.5 |
| Remission (MADRS <= 10) | Twice weekly | 18.0 | 13.0 |
| Response (>= 50% reduction) | Three times weekly | 25.0 | 25.0 |
| Response (>= 50% reduction) | Twice weekly | 16.5 | 15.0 |
cmp_val <- function(tgt, reg) {
  v <- regimen_cmp$sim[regimen_cmp$target == tgt & regimen_cmp$regimen == reg]
  if (length(v) != 1L) stop("no unique row for ", tgt, " / ", reg)
  v
}
stopifnot(
  # 200 patients per regimen: the binomial SE of a 20-25% proportion is about
  # 3 points, so 10 points is >= 3 SE. A mis-transcribed EC50 (0.439 ng/mL),
  # turnover time or baseline moves these peaks by far more.
  abs(cmp_val("Response (>= 50% reduction)", "Twice weekly") - 16.5) < 10,
  abs(cmp_val("Response (>= 50% reduction)", "Three times weekly") - 25) < 10,
  abs(cmp_val("Remission (MADRS <= 10)", "Twice weekly") - 18) < 10,
  abs(cmp_val("Remission (MADRS <= 10)", "Three times weekly") - 26) < 10,
  # Medians of per-patient maxima; the paper gives upper bounds of 10% (BP)
  # and 6.5% (HR), and its Figure S6 bottom panels peak at about these values.
  cmp_val("Median maximum % increase in MAP", "Twice weekly") < 14,
  cmp_val("Median maximum % increase in HR", "Twice weekly") < 9.5
)
The response and remission peaks after the day-15 dose and the median maximum increases in blood pressure and heart rate agree with the paper. The median percentage decrease in MADRS at day 15 (paper 11.5% and 18.3%) is not reproduced exactly: before the day-15 dose the simulation gives 7.5% and 12.5%, and the value climbs steeply within hours of the dose. The paper does not say at what time on day 15 the decrease was read, and the medians of the MADRS curves in Figures S6 and S7 at the day-15 dose (about 21 and 19 points against a baseline of about 23) agree with the simulated curves above, so the difference is in the unstated read-out time rather than in the model. It is left out of the assertions.
Daily s.c. dosing (Table S3)
Table S3 reports, for once-daily s.c. ketamine for 7 days (1000 simulated patients), the percentage of patients meeting the MADRS targets by day and the maximum percentage increase in blood pressure and heart rate. The day of Table S3 is read here as the time after the first dose in whole days (day 0 is the pre-dose baseline, day 1 is 24 h after the first dose, just before the second), since the paper does not state the read-out time within a day.
make_sc_daily <- function(mg_per_kg, n, id_offset, obs_cmt, obs_dvid) {
  ids <- id_offset + seq_len(n)
  dose <- expand.grid(id = ids, time = (0:6) * 24)
  dose$amt <- dose_ug(mg_per_kg)
  dose$rate <- 0
  dose$evid <- 1L
  dose$cmt <- "depot"
  dose$dvid <- NA_integer_
  times <- sort(unique(c(seq(0, 7 * 24, by = 0.25))))
  obs <- expand.grid(id = ids, time = times)
  obs$amt <- NA_real_
  obs$rate <- NA_real_
  obs$evid <- 0L
  obs$cmt <- obs_cmt
  obs$dvid <- obs_dvid
  out <- dplyr::bind_rows(dose, obs) |>
    dplyr::arrange(id, time, dplyr::desc(evid))
  out$WT <- wt_ref
  out$dose_group <- paste(mg_per_kg, "mg/kg s.c. daily")
  out
}
n_sc <- 200L
build_sc <- function(obs_cmt, obs_dvid) {
  dplyr::bind_rows(
    make_sc_daily(0.1, n_sc, 0L, obs_cmt, obs_dvid),
    make_sc_daily(0.3, n_sc, n_sc, obs_cmt, obs_dvid),
    make_sc_daily(0.5, n_sc, 2L * n_sc, obs_cmt, obs_dvid)
  )
}
ev_sc_madrs <- build_sc("madrs", NA_integer_)
ev_sc_alg <- build_sc("central", 1L)
stopifnot(!anyDuplicated(unique(ev_sc_madrs[, c("id", "time", "evid")])))
rxode2::rxSetSeed(20220922)
sc_madrs <- rxode2::rxSolve(mods$madrs, events = ev_sc_madrs, keep = "dose_group", useLinCmt = FALSE, returnType = "data.frame")
sc_map <- rxode2::rxSolve(mods$map, events = ev_sc_alg, keep = "dose_group", useLinCmt = FALSE, returnType = "data.frame")
sc_hr <- rxode2::rxSolve(mods$hr, events = ev_sc_alg, keep = "dose_group", useLinCmt = FALSE, returnType = "data.frame")

sc_targets <- sc_madrs |>
  dplyr::group_by(id) |>
  dplyr::mutate(base = madrs[time == 0]) |>
  dplyr::ungroup() |>
  dplyr::filter(time %in% ((0:7) * 24)) |>
  dplyr::group_by(dose_group, day = time / 24) |>
  dplyr::summarise(
    resp_sim = 100 * mean(100 * (base - madrs) / base >= 50),
    remis_sim = 100 * mean(madrs <= 10),
    .groups = "drop"
  )
sc_max <- function(df, var) {
  df |>
    dplyr::group_by(dose_group, id) |>
    dplyr::summarise(pct = 100 * (max(.data[[var]]) - .data[[var]][time == 0]) / .data[[var]][time == 0], .groups = "drop") |>
    dplyr::group_by(dose_group) |>
    dplyr::summarise(sim = median(pct), .groups = "drop")
}
table_s3 <- tibble::tribble(
  ~dose_group, ~day, ~resp_paper, ~remis_paper,
  "0.1 mg/kg s.c. daily", 1, 0.5, 2.6,
  "0.1 mg/kg s.c. daily", 3, 6.9, 9.4,
  "0.1 mg/kg s.c. daily", 7, 16, 17,
  "0.3 mg/kg s.c. daily", 1, 5.2, 7.3,
  "0.3 mg/kg s.c. daily", 3, 28, 26,
  "0.3 mg/kg s.c. daily", 7, 46, 38,
  "0.5 mg/kg s.c. daily", 1, 7.0, 9.5,
  "0.5 mg/kg s.c. daily", 3, 35, 33,
  "0.5 mg/kg s.c. daily", 7, 55, 50
)
s3_cmp <- table_s3 |>
  dplyr::left_join(sc_targets, by = c("dose_group", "day"))
s3_cmp |>
  dplyr::rename(
    "Regimen" = dose_group, "Day" = day,
    "Response, paper (%)" = resp_paper, "Response, simulated (%)" = resp_sim,
    "Remission, paper (%)" = remis_paper, "Remission, simulated (%)" = remis_sim
  ) |>
knitr::kable(digits = 1, caption = "Percentage of patients with >= 50% MADRS reduction or MADRS <= 10 on daily s.c. ketamine: Table S3 of Abuhelwa 2022 vs. this simulation ('<1' in Table S3 is shown as 0.5).")| Regimen | Day | Response, paper (%) | Remission, paper (%) | Response, simulated (%) | Remission, simulated (%) |
|---|---|---|---|---|---|
| 0.1 mg/kg s.c. daily | 1 | 0.5 | 2.6 | 0.5 | 3.0 |
| 0.1 mg/kg s.c. daily | 3 | 6.9 | 9.4 | 5.0 | 9.0 |
| 0.1 mg/kg s.c. daily | 7 | 16.0 | 17.0 | 13.0 | 19.0 |
| 0.3 mg/kg s.c. daily | 1 | 5.2 | 7.3 | 3.0 | 6.0 |
| 0.3 mg/kg s.c. daily | 3 | 28.0 | 26.0 | 24.5 | 19.5 |
| 0.3 mg/kg s.c. daily | 7 | 46.0 | 38.0 | 36.5 | 31.5 |
| 0.5 mg/kg s.c. daily | 1 | 7.0 | 9.5 | 11.0 | 10.5 |
| 0.5 mg/kg s.c. daily | 3 | 35.0 | 33.0 | 37.0 | 33.0 |
| 0.5 mg/kg s.c. daily | 7 | 55.0 | 50.0 | 59.0 | 53.5 |
s3_cv <- dplyr::left_join(
  sc_max(sc_map, "map") |> dplyr::rename(map_sim = sim),
  sc_max(sc_hr, "hr") |> dplyr::rename(hr_sim = sim),
  by = "dose_group"
) |>
  dplyr::left_join(
    tibble::tribble(
      ~dose_group, ~map_paper, ~hr_paper,
      "0.1 mg/kg s.c. daily", 0.5, 0.5,
      "0.3 mg/kg s.c. daily", 2, 2.3,
      "0.5 mg/kg s.c. daily", 5.3, 3.9
    ),
    by = "dose_group"
  )
s3_cv |>
  dplyr::select(dose_group, map_paper, map_sim, hr_paper, hr_sim) |>
  dplyr::rename(
    "Regimen" = dose_group,
    "Max % increase MAP, paper" = map_paper, "Max % increase MAP, simulated (median)" = map_sim,
    "Max % increase HR, paper" = hr_paper, "Max % increase HR, simulated (median)" = hr_sim
  ) |>
knitr::kable(digits = 1, caption = "Maximum percentage increase in mean arterial pressure and heart rate on daily s.c. ketamine: Table S3 of Abuhelwa 2022 vs. this simulation.")| Regimen | Max % increase MAP, paper | Max % increase MAP, simulated (median) | Max % increase HR, paper | Max % increase HR, simulated (median) |
|---|---|---|---|---|
| 0.1 mg/kg s.c. daily | 0.5 | 0.2 | 0.5 | 0.8 |
| 0.3 mg/kg s.c. daily | 2.0 | 1.8 | 2.3 | 2.1 |
| 0.5 mg/kg s.c. daily | 5.3 | 5.0 | 3.9 | 4.2 |
s3_day7 <- s3_cmp |> dplyr::filter(day == 7)
stopifnot(
  nrow(s3_day7) == 3L,
  # Day-7 response and remission: 200 patients per arm gives a binomial SE of
  # at most 3.5 points; 15 points still breaks on a tenfold EC50 or a wrong
  # bioavailability, which shift these by 20-40 points.
  all(abs(s3_day7$resp_sim - s3_day7$resp_paper) < 15),
  all(abs(s3_day7$remis_sim - s3_day7$remis_paper) < 15),
  # Dose ordering of the cardiovascular effect at the extremes of the dose
  # range (the 0.1 and 0.5 mg/kg medians differ several-fold).
  s3_cv$map_sim[s3_cv$dose_group == "0.5 mg/kg s.c. daily"] > s3_cv$map_sim[s3_cv$dose_group == "0.1 mg/kg s.c. daily"],
  all(s3_cv$map_sim < 10),
  all(s3_cv$hr_sim < 8)
)
Read at whole multiples of 24 h, the simulated percentages track Table S3 at every dose and day. With 2000 virtual patients per arm (run by the maintainers outside this article) the day-7 values are 16, 43 and 56% responders and 18, 38 and 50% remitters at 0.1, 0.3 and 0.5 mg/kg, against 16, 46 and 55% and 17, 38 and 50% in Table S3; the 200-patient arms above scatter about these by a few points.
Assumptions and deviations
-
Heart-rate random effect. Table 3 and the Results
put the second HR random effect (156 %CV) on EC50, while the HR control
stream in Supplement S1 puts it on the maximum attainable heart rate
(
TVEMAX = THETA(19) * EXP(ETA(7))). The PD control streams in Supplement S1 also carry the initial, not final, PD estimates, so they are a development snapshot of the PD models. The maintainers followed Table 3: with the eta on the 220 beats/min ceiling, the 95th percentile of heart rate at the end of a 0.5 mg/kg 40-min infusion is about 155 beats/min, against about 120 beats/min in the paper’s own simulated 90% band (Figures S6 and S7); with the eta on EC50 it is about 122 beats/min. -
MADRS equation. The printed equation for
d(MADRS)/dt in Methods reads
Kin0 - Kout * Edrug, which is not a function of the MADRS state. The model usesKin - Kout * MADRSwithKin = Kin0 * (1 - Edrug), as in the turnover description in the text and the supplementary$DES(DADT(7) = KIN - KOUT*A(7)). - Turnover time. The paper estimates the turnover time TURN = 1/kout with a log-normal random effect; the model is parameterised in kout = 1/TURN, which leaves the distribution unchanged (the eta only changes sign).
-
Norketamine units. The fraction of ketamine
metabolised to norketamine could not be estimated and was fixed to 1,
and the formation flux is carried in ketamine mass units without a
molecular-weight correction, as in the supplementary
$DES. Norketamine concentrations and parameters are therefore apparent values (CL/fm, V/fm) in ketamine-equivalent ng/mL. -
Single absorption depot. The NONMEM code has
separate s.c. and i.m. depots with identical KA and F; one
depotcompartment is equivalent. -
Residual error. The paper’s combined residual error
sqrt((prop * IPRED)^2 + add^2)is theadd() + prop()form. The ketamine additive term (0.00001 ng/mL) and the PD proportional terms (0.0001) were held constant at near-zero values in the source and are kept as such. - Virtual cohort. Body weight is not reported, so all virtual patients weigh 70 kg (the allometric reference). Dosing is in mg/kg, so the weight affects exposure only through the 0.75 clearance exponent. The i.v. doses of the original study (injections) are not described in detail; the i.v. simulations use the 40-min infusion of the paper’s own dosing simulations.
- Simulation read-outs. The paper does not state the time within day 15 at which its median MADRS decrease was read, nor the read-out time within each day of Table S3. The comparisons above state the read-out used; the day-15 median decrease is reported but not asserted.
- No erratum or correction notice for this article was found in Europe PMC (checked 2026-10-09).