Model and source
- Citation: Smit C, Hofmann D, Sayasone S, Keiser J, Pfister M (2022). Characterization of the Population Pharmacokinetics of Moxidectin in Adults Infected with Strongyloides Stercoralis: Support for a Fixed-Dose Treatment Regimen. Clin Pharmacokinet 61:123-132. doi:10.1007/s40262-021-01048-4
- Description: Two-compartment population PK model for oral moxidectin in 96 Strongyloides stercoralis-infected adults in Laos (single 2-12 mg doses; capillary whole-blood volumetric microsamples). First-order absorption from a depot compartment after an absorption lag time, linear elimination, allometric body-weight scaling (exponents fixed at 0.75 on CL/F and Q/F and 1 on V1/F and V2/F, reference 70 kg) and a power effect of age on the central volume (reference 44.25 years). Log-normal IIV on all six structural parameters (lag-time IIV fixed) and proportional residual error.
- Article (open access): https://doi.org/10.1007/s40262-021-01048-4
- Electronic Supplementary Material (same landing page): Figures S1-S5, Tables S1-S3 (assay performance and the simulated AUC and Cmax by weight group) and the MLXTRAN code of the final Monolix model.
Smit 2022 is the first population PK analysis of moxidectin in humans and the first in patients. The model was fitted with SAEM in Monolix 2019R2. The published MLXTRAN code fixes the structure (compartments, lag-time implementation, covariate centring, error model), and Table 2 supplies the final estimates.
Population
Ninety-six Strongyloides stercoralis-infected adults in NamBak District, northern Laos, took part in a PK sub-study of a phase IIa randomized, placebo-controlled dose-escalation trial (NCT04056325; November 2019 - March 2020). Each received one oral dose of 2, 4, 6, 8, 10 or 12 mg moxidectin (2 mg tablets) after a local lunch; the arms held 15, 16, 14, 21, 15 and 15 participants. Median age was 45.0 years (range 22-65), median total body weight 56.2 kg (range 36.2-82.6), median BMI 22.2 kg/m^2 (17.0-32.3), and 37 (39%) were female. Baseline infection intensity was light in 16.7%, moderate in 39.6% and heavy in 43.6% (Smit 2022 Table 1).
Capillary blood was collected with 30 uL volumetric absorptive microsamples (Mitra) at 2, 4, 6 and 7 h and 1, 3, 7 and 28 days post-dose. The assay LLOQ was 1.5 ng/mL; 158 of the 762 samples (20.7%) were below it and were kept in the fit through Monolix’s censored-data likelihood. Concentrations are therefore whole-blood concentrations.
The same information is available programmatically via
readModelDb("Smit_2022_moxidectin")()$population.
Source trace
| Equation / parameter | Value | Source location |
|---|---|---|
ltlag (Tlag) |
log(1.64 h) | Table 2 |
lka (Ka) |
log(3.38 1/h) | Table 2 |
lcl (CL/F, 70 kg) |
log(4.47 L/h) | Table 2 |
lvc (V1/F, 70 kg, 44.25 y) |
log(136 L) | Table 2 |
lq (Q/F, 70 kg) |
log(10.0 L/h) | Table 2 |
lvp (V2/F, 70 kg) |
log(1172 L) | Table 2 |
e_wt_cl, e_wt_q
|
0.75 (fixed) | Table 2; MLXTRAN beta_CL_logtWT,
beta_Q_logtWT method=FIXED |
e_wt_vc, e_wt_vp
|
1 (fixed) | Table 2; MLXTRAN beta_V1_logtWT,
beta_V2_logtWT method=FIXED |
e_age_vc |
-0.422 | Results 3.2 (Table 2 rounds to -0.42) |
| Weight reference | 70 kg | MLXTRAN logtWT = log(WT/70); Table 2 footnote a |
| Age reference | 44.2517 years | MLXTRAN logtAGE = log(AGE/44.2517); Table 2 legend
rounds to 44.3 |
etaltlag |
0.1^2 (fixed) | Table 2 (omega = SD); MLXTRAN omega_Tlag
method=FIXED |
etalka |
0.672^2 | Table 2 |
etalcl |
0.625^2 | Table 2 |
etalvc |
0.297^2 | Table 2 |
etalq |
0.343^2 | Table 2 |
etalvp |
0.779^2 | Table 2 |
propSd |
0.165 | Table 2, footnote b (SD) |
d/dt(depot), d/dt(central),
d/dt(peripheral1)
|
n/a | MLXTRAN model text ddt_Ad, ddt_Ac,
ddt_Ap
|
| Lag time | n/a | MLXTRAN if (t < Tlag) KA = 0
|
| Error model | n/a | MLXTRAN errorModel = proportional(b)
|
Typical-value checks against the paper’s own numbers
The paper reports three derived typical values: the terminal half-life of a 70 kg adult aged 44.3 years (278 h, Results 3.2), and V1/F of a 70 kg adult aged 18 and 65 years (199 L and 116 L, Results 3.2). The half-life follows in closed form from the typical micro-constants.
mod <- readModelDb("Smit_2022_moxidectin")
p <- mod()$theta
cl <- exp(p[["lcl"]]); v1 <- exp(p[["lvc"]]); q <- exp(p[["lq"]]); v2 <- exp(p[["lvp"]])
ageref <- 44.2517
k10 <- cl / v1; k12 <- q / v1; k21 <- q / v2
a <- k10 + k12 + k21
beta <- (a - sqrt(a^2 - 4 * k10 * k21)) / 2
v1_age <- function(age) v1 * (age / ageref)^p[["e_age_vc"]]

typ <- tibble::tibble(
  Quantity = c("Terminal half-life, 70 kg, 44.3 y (h)",
               "V1/F, 70 kg, 18 y (L)", "V1/F, 70 kg, 65 y (L)"),
  Published = c(278, 199, 116),
  Model = c(log(2) / beta, v1_age(18), v1_age(65))
) |>
  mutate(`% diff` = 100 * (Model - Published) / Published)
knitr::kable(typ, digits = 1)| Quantity | Published | Model | % diff |
|---|---|---|---|
| Terminal half-life, 70 kg, 44.3 y (h) | 278 | 277.9 | 0.0 |
| V1/F, 70 kg, 18 y (L) | 199 | 198.8 | -0.1 |
| V1/F, 70 kg, 65 y (L) | 116 | 115.6 | -0.3 |
# Pure arithmetic on the published estimates: must agree to rounding.
stopifnot(all(abs(typ$`% diff`) < 1))
(At 44.3 rather than 44.2517 years the half-life is unchanged, because age acts only on V1/F and the terminal phase is dominated by V2/F.)
Virtual cohort
The observed data are not public. Two virtual cohorts are used:
- Trial cohort – the six dose arms of the study, 100 participants per arm, with body weight drawn from a normal distribution (mean 56.5 kg, SD 8.5 kg) truncated to the observed 36.2-82.6 kg range and age from a normal distribution (mean 45.5 years, SD 10 years) truncated to 22-65 years. These approximate the Table 1 medians and interquartile ranges.
-
Dosing-strategy cohort – the Smit 2022 simulation
design (Methods 2.4, Tables S2-S3): body weight uniform within each 10
kg band from 30 to 90 kg, age uniform 18-65 years, and either an 8 mg
fixed dose or the weight-based dose of Eqs. 3-4,
DOSE = 8 * DW / DW56withDW = 70 * (WT/70)^0.75, which is8 * (WT/56)^0.75mg. The paper used 5000 subjects per strategy; here 200 per weight band per strategy.
set.seed(20220723)
rxode2::rxSetSeed(20220723)

rtrunc_norm <- function(n, mean, sd, lo, hi) {
  x <- stats::rnorm(n, mean, sd)
  bad <- x < lo | x > hi
  while (any(bad)) {
    x[bad] <- stats::rnorm(sum(bad), mean, sd)
    bad <- x < lo | x > hi
  }
  x
}

# Dense over absorption and the peak (Tlag 1.64 h, Ka 3.38 /h), then sparse
# out to 12 weeks (about 7 terminal half-lives) so PKNCA's AUCinf
# extrapolation is small. Includes every nominal sampling time of the study.
obs_times <- c(0, seq(0.5, 8, by = 0.5), 10, 12, 16, 20, 24, 36, 48, 72, 96,
               120, 168, 240, 336, 504, 672, 1008, 1344, 1680, 2016)

make_events <- function(subj) {
  dose <- subj |>
    mutate(time = 0, evid = 1L, amt = dose_mg, cmt = "depot")
  obs <- subj |>
    tidyr::crossing(time = obs_times) |>
    mutate(evid = 0L, amt = 0, cmt = "central")
  bind_rows(dose, obs) |>
    arrange(id, time, desc(evid))
}

n_arm <- 100L
doses <- c(2, 4, 6, 8, 10, 12)
trial_subj <- tibble::tibble(
  id = seq_len(n_arm * length(doses)),
  dose_mg = rep(doses, each = n_arm),
  WT = rtrunc_norm(n_arm * length(doses), 56.5, 8.5, 36.2, 82.6),
  AGE = rtrunc_norm(n_arm * length(doses), 45.5, 10, 22, 65)
) |>
  mutate(treatment = factor(paste(dose_mg, "mg"), levels = paste(doses, "mg")))
trial_events <- make_events(trial_subj)

n_band <- 200L
bands <- tibble::tibble(lo = seq(30, 80, by = 10), hi = lo + 10) |>
  mutate(band = paste(lo, "-", hi))
strategy_subj <- tidyr::crossing(
  bands,
  regimen = c("8 mg fixed dose", "Weight-based dosing"),
  k = seq_len(n_band)
) |>
  mutate(
    id = 10000L + dplyr::row_number(),
    WT = stats::runif(dplyr::n(), lo, hi),
    AGE = stats::runif(dplyr::n(), 18, 65),
    dose_mg = ifelse(regimen == "8 mg fixed dose", 8, 8 * (WT / 56)^0.75),
    group = paste(regimen, band, sep = " | ")
  ) |>
  select(id, WT, AGE, dose_mg, band, regimen, group)
strategy_events <- make_events(strategy_subj)

stopifnot(
  !anyDuplicated(unique(trial_events[, c("id", "time", "evid")])),
  !anyDuplicated(unique(strategy_events[, c("id", "time", "evid")])),
  !any(trial_subj$id %in% strategy_subj$id)
)Replicate published figures
Figure 1 – concentration-time profiles by dose group
Smit 2022 Figure 1 is a prediction-corrected VPC by dose group with the fraction below the LLOQ underneath. Without the observed data a pcVPC cannot be rebuilt; the figure below shows the simulated 5th, 50th and 95th percentiles of whole-blood concentration by dose group over the 28-day sampling window, with the 1.5 ng/mL LLOQ, as the model-side counterpart of the upper panels.
lloq <- 1.5
sim_trial |>
  filter(time > 0, time <= 672) |>
  group_by(treatment, time) |>
  summarise(
    Q05 = quantile(Cc, 0.05), Q50 = quantile(Cc, 0.50), Q95 = quantile(Cc, 0.95),
    .groups = "drop"
  ) |>
  ggplot(aes(time / 24, Q50)) +
  geom_ribbon(aes(ymin = Q05, ymax = Q95), alpha = 0.25) +
  geom_line() +
  geom_hline(yintercept = lloq, linetype = "dashed") +
  facet_wrap(~treatment) +
  scale_y_log10() +
  labs(x = "Time after dose (days)", y = "Moxidectin whole-blood concentration (ng/mL)",
       caption = "Replicates the upper panels of Figure 1 of Smit 2022 (model percentiles only).")
#> Warning in scale_y_log10(): log-10 transformation introduced infinite values.
#> log-10 transformation introduced infinite values.
#> log-10 transformation introduced infinite values.
#> log-10 transformation introduced infinite values.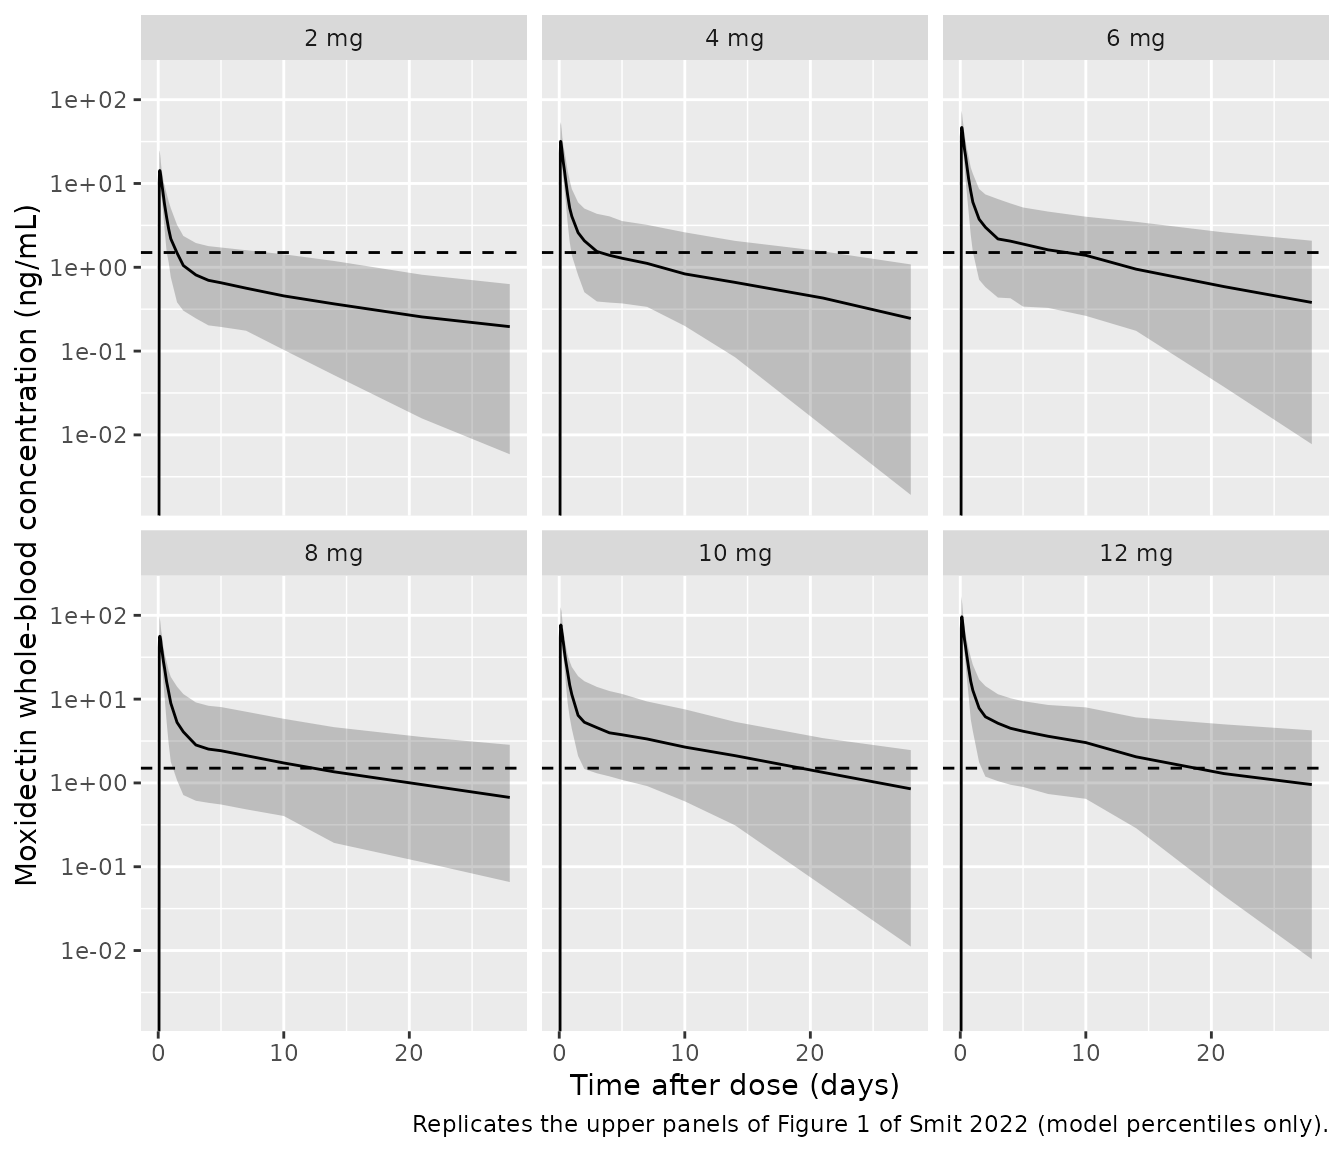
The lower panels of Figure 1 show the fraction of samples below the LLOQ at each nominal time. The simulated fraction (with residual error) is:
nominal <- c(2, 4, 6, 7, 24, 72, 168, 672)
blq <- sim_trial |>
  filter(time %in% nominal) |>
  group_by(treatment, time) |>
  summarise(pct_blq = round(100 * mean(sim < lloq)), .groups = "drop") |>
  tidyr::pivot_wider(names_from = time, values_from = pct_blq, names_prefix = "t = ")
knitr::kable(blq, caption = "Simulated % of samples below the 1.5 ng/mL LLOQ, by dose group and nominal time (h).")| treatment | t = 2 | t = 4 | t = 6 | t = 7 | t = 24 | t = 72 | t = 168 | t = 672 |
|---|---|---|---|---|---|---|---|---|
| 2 mg | 4 | 0 | 0 | 0 | 30 | 88 | 91 | 100 |
| 4 mg | 1 | 0 | 0 | 0 | 6 | 44 | 64 | 97 |
| 6 mg | 2 | 0 | 0 | 0 | 7 | 35 | 49 | 84 |
| 8 mg | 3 | 0 | 0 | 0 | 2 | 28 | 37 | 74 |
| 10 mg | 3 | 0 | 0 | 0 | 0 | 7 | 21 | 76 |
| 12 mg | 5 | 0 | 0 | 0 | 1 | 7 | 18 | 63 |
Across the design the observed BLQ fraction was 20.7% (158 of 762 samples, Results 3.1). The simulated fraction over the same eight nominal times and the Table 1 arm sizes is:
arm_n <- c(`2 mg` = 15, `4 mg` = 16, `6 mg` = 14, `8 mg` = 21, `10 mg` = 15, `12 mg` = 15)
blq_overall <- sim_trial |>
  filter(time %in% nominal) |>
  group_by(treatment) |>
  summarise(frac = mean(sim < lloq), .groups = "drop") |>
  mutate(w = arm_n[as.character(treatment)]) |>
  summarise(pct = 100 * sum(frac * w) / sum(w))
blq_overall
#> # A tibble: 1 × 1
#>     pct
#>   <dbl>
#> 1  21.6
# Whole-design BLQ fraction: the observed 20.7% is a single realisation of
# 96 subjects; allow a wide envelope. A 2-fold error in CL or V2 moves this
# far outside the band.
stopifnot(blq_overall$pct > 10, blq_overall$pct < 35)
Figure 2 and Figure S5 – AUCinf and Cmax by weight group and strategy
nca_one <- function(sim, grp) {
  conc <- sim |>
    filter(group == grp, !is.na(Cc)) |>
    select(id, time, Cc, group)
  dose <- strategy_events |>
    filter(group == grp, evid == 1) |>
    select(id, time, amt, group)
  PKNCA::pk.nca(PKNCA::PKNCAdata(
    PKNCA::PKNCAconc(conc, Cc ~ time | group + id),
    PKNCA::PKNCAdose(dose, amt ~ time | group + id),
    intervals = data.frame(start = 0, end = Inf, cmax = TRUE, aucinf.obs = TRUE)
  ))$result
}
# One pk.nca() call per group keeps PKNCA fast (its cost grows faster than
# linearly with the number of subject-intervals in a single call).
nca_strat <- bind_rows(lapply(unique(strategy_subj$group), nca_one, sim = sim_strat)) |>
  select(id, group, PPTESTCD, PPORRES) |>
  tidyr::pivot_wider(names_from = PPTESTCD, values_from = PPORRES) |>
  left_join(strategy_subj |> select(id, band, regimen), by = "id")
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
ggplot(nca_strat, aes(band, aucinf.obs, fill = regimen)) +
  geom_boxplot(outlier.size = 0.5) +
  scale_fill_manual(values = c("grey20", "grey70")) +
  labs(x = "Body weight group (kg)", y = "AUCinf (ng*h/mL)", fill = NULL,
       caption = "Replicates Figure 2 of Smit 2022.")
#> Warning: Removed 29 rows containing non-finite outside the scale range
#> (`stat_boxplot()`).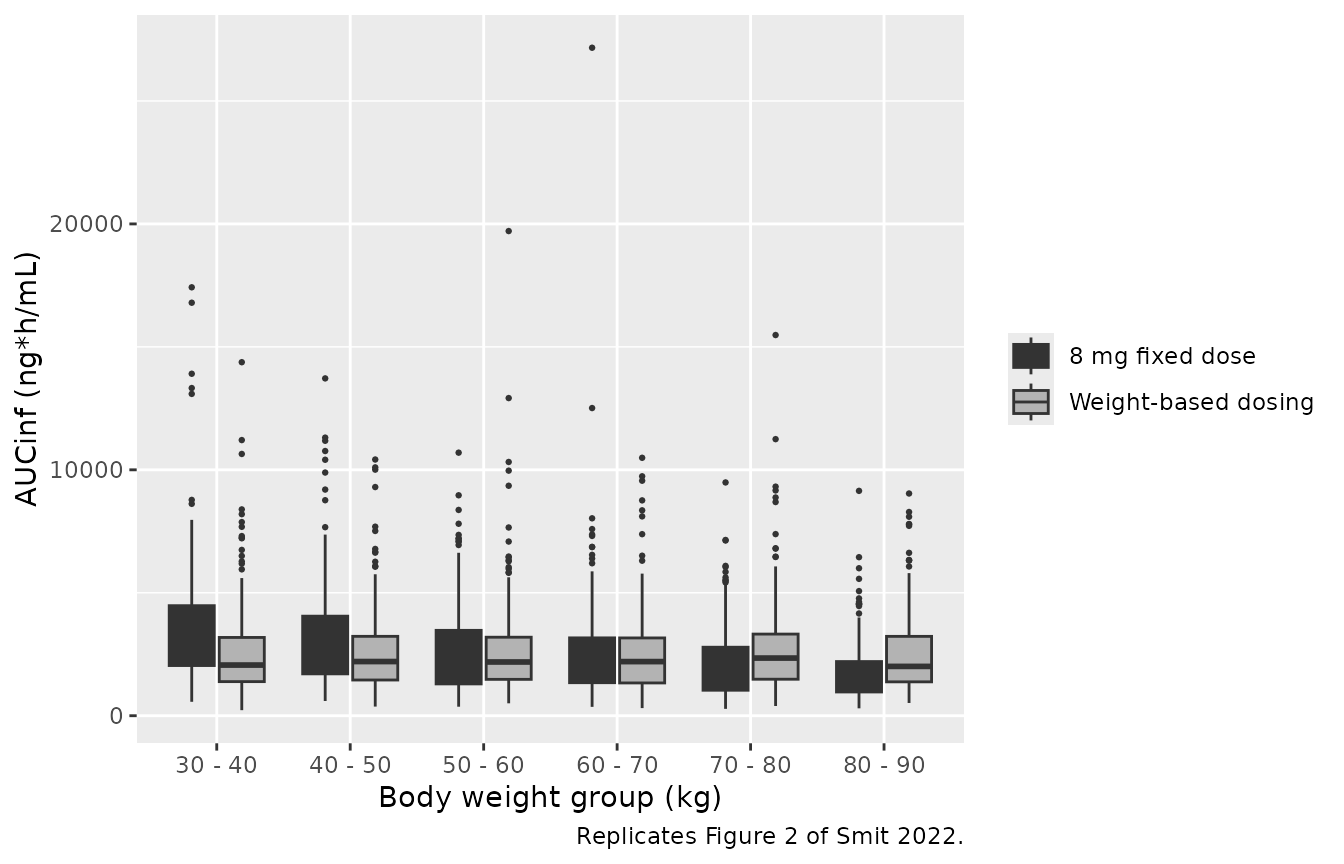
ggplot(nca_strat, aes(band, cmax, fill = regimen)) +
  geom_boxplot(outlier.size = 0.5) +
  scale_fill_manual(values = c("grey20", "grey70")) +
  labs(x = "Body weight group (kg)", y = "Cmax (ng/mL)", fill = NULL,
       caption = "Replicates Figure S5 of Smit 2022.")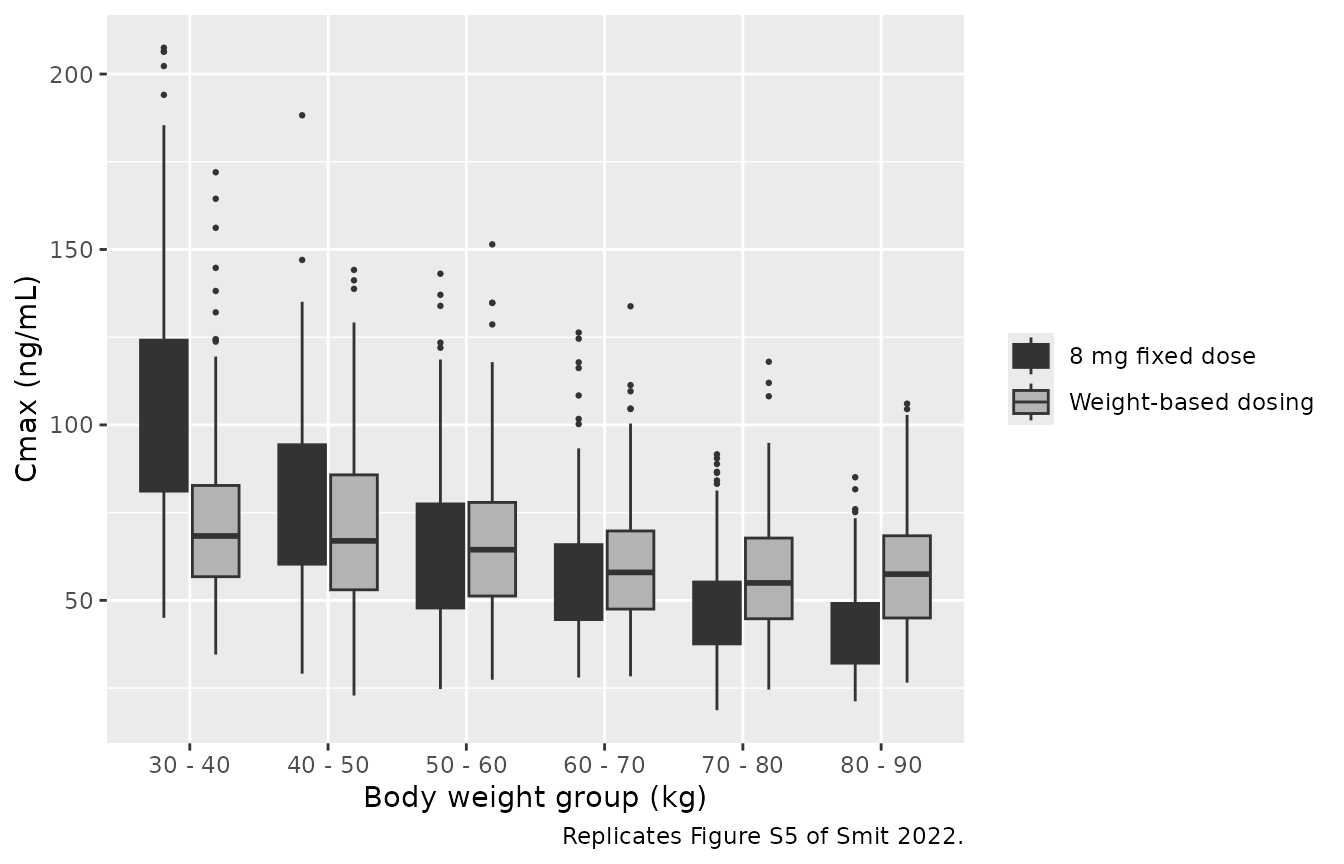
PKNCA validation
Trial cohort by dose group
nca_arm <- function(trt) {
  conc <- sim_trial |>
    filter(treatment == trt, !is.na(Cc)) |>
    select(id, time, Cc, treatment)
  dose <- trial_events |>
    filter(treatment == trt, evid == 1) |>
    select(id, time, amt, treatment)
  PKNCA::pk.nca(PKNCA::PKNCAdata(
    PKNCA::PKNCAconc(conc, Cc ~ time | treatment + id),
    PKNCA::PKNCAdose(dose, amt ~ time | treatment + id),
    intervals = data.frame(start = 0, end = Inf, cmax = TRUE, tmax = TRUE,
                           aucinf.obs = TRUE, half.life = TRUE)
  ))$result
}
nca_trial <- bind_rows(lapply(levels(trial_subj$treatment), nca_arm)) |>
  filter(PPTESTCD %in% c("cmax", "tmax", "aucinf.obs", "half.life"))
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc = conc): Negative concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(data$conc): NaNs produced
#> Warning in assert_conc(conc, any_missing_conc = any_missing_conc): Negative
#> concentrations found
#> Warning in log(conc.2/conc.1): NaNs produced

nca_trial |>
  group_by(treatment, PPTESTCD) |>
  summarise(median = median(PPORRES, na.rm = TRUE), .groups = "drop") |>
  tidyr::pivot_wider(names_from = PPTESTCD, values_from = median) |>
  dplyr::rename(
    "Dose group" = treatment, "Cmax (ng/mL)" = cmax, "Tmax (h)" = tmax,
    "AUCinf (ng*h/mL)" = aucinf.obs, "t1/2 (h)" = half.life
  ) |>
knitr::kable(digits = 1, caption = "Median simulated NCA by dose group (trial cohort).")| Dose group | AUCinf (ng*h/mL) | Cmax (ng/mL) | t1/2 (h) | Tmax (h) |
|---|---|---|---|---|
| 2 mg | 622.2 | 15.1 | 330.0 | 2.5 |
| 4 mg | 1153.8 | 32.6 | 244.2 | 2.5 |
| 6 mg | 1466.5 | 49.5 | 295.8 | 2.5 |
| 8 mg | 2255.2 | 57.8 | 332.2 | 3.0 |
| 10 mg | 3030.0 | 79.6 | 261.5 | 3.0 |
| 12 mg | 3272.7 | 98.9 | 294.2 | 2.5 |
The paper does not tabulate NCA by dose group, but it computes each
subject’s exposure as AUCinf = DOSE / (CL/F) (Eq. 5). The
PKNCA AUCinf of each simulated profile must agree with that closed form
evaluated at the same subject’s clearance; the difference is only
trapezoid and terminal extrapolation error.
cl_i <- sim_trial |> distinct(id, cl, dose_mg)
eq5 <- nca_trial |>
  filter(PPTESTCD == "aucinf.obs") |>
  left_join(cl_i, by = "id") |>
  mutate(auc_eq5 = 1000 * dose_mg / cl, pct_diff = 100 * (PPORRES - auc_eq5) / auc_eq5)
# A few subjects drawn with a very large V2/F and small Q/F have not reached
# their terminal phase by 12 weeks, and PKNCA returns a non-finite AUCinf for
# them; they are counted and excluded.
n_nonfinite <- sum(!is.finite(eq5$PPORRES))
n_nonfinite
#> [1] 3
eq5 <- filter(eq5, is.finite(pct_diff))
summary(eq5$pct_diff)
#>     Min.  1st Qu.   Median     Mean  3rd Qu.     Max.
#> -1.08926  0.09994  0.20545  0.20098  0.31615  1.26471
# Same drawn parameters on both sides, so the difference is only numerical
# (trapezoid and extrapolation): the bounds can be tight. Realised median
# about 0.2%, 90th percentile of |diff| about 0.5%.
stopifnot(
  n_nonfinite <= 0.05 * nrow(trial_subj),
  abs(median(eq5$pct_diff)) < 2,
  quantile(abs(eq5$pct_diff), 0.9) < 5
)
Comparison against the published simulations (Tables S2 and S3)
Tables S2 and S3 of the supplement report the simulated AUCinf and Cmax of the two dosing strategies by 10 kg weight group as “mean +/- SD”. The comparison below uses the simulated mean Cmax and the simulated median AUCinf (see the note that follows the table for why).
published <- tibble::tribble(
  ~group,                                ~cmax, ~aucinf.obs,
  "8 mg fixed dose | 30 - 40",            97.7, 3099,
  "8 mg fixed dose | 40 - 50",            74.8, 2468,
  "8 mg fixed dose | 50 - 60",            61.1, 2083,
  "8 mg fixed dose | 60 - 70",            53.3, 1907,
  "8 mg fixed dose | 70 - 80",            47.1, 1690,
  "8 mg fixed dose | 80 - 90",            40.4, 1553,
  "Weight-based dosing | 30 - 40",        68.0, 2119,
  "Weight-based dosing | 40 - 50",        64.2, 2126,
  "Weight-based dosing | 50 - 60",        62.0, 2269,
  "Weight-based dosing | 60 - 70",        59.7, 2175,
  "Weight-based dosing | 70 - 80",        57.6, 2049,
  "Weight-based dosing | 80 - 90",        55.5, 2143
)
simulated <- nca_strat |>
  group_by(group) |>
  summarise(cmax = mean(cmax), aucinf.obs = median(aucinf.obs[is.finite(aucinf.obs)]),
            .groups = "drop")

cmp <- nlmixr2lib::ncaComparisonTable(
  simulated = simulated,
  reference = published,
  by = "group",
  units = c(cmax = "ng/mL", aucinf.obs = "ng*h/mL"),
  tolerance_pct = 20
)
knitr::kable(
  cmp,
  caption = paste(
    "Simulated vs. Smit 2022 Tables S2-S3 (Cmax: simulated mean; AUCinf:",
    "simulated median). * differs from reference by >20%."
  )
)| NCA parameter | group | Reference | Simulated | % diff |
|---|---|---|---|---|
| Cmax (ng/mL) | 8 mg fixed dose | 30 - 40 | 97.7 | 105 | +7.1% |
| Cmax (ng/mL) | 8 mg fixed dose | 40 - 50 | 74.8 | 79.7 | +6.5% |
| Cmax (ng/mL) | 8 mg fixed dose | 50 - 60 | 61.1 | 64.8 | +6.1% |
| Cmax (ng/mL) | 8 mg fixed dose | 60 - 70 | 53.3 | 57.5 | +7.8% |
| Cmax (ng/mL) | 8 mg fixed dose | 70 - 80 | 47.1 | 47.9 | +1.7% |
| Cmax (ng/mL) | 8 mg fixed dose | 80 - 90 | 40.4 | 41.7 | +3.2% |
| Cmax (ng/mL) | Weight-based dosing | 30 - 40 | 68 | 72.9 | +7.3% |
| Cmax (ng/mL) | Weight-based dosing | 40 - 50 | 64.2 | 70.4 | +9.7% |
| Cmax (ng/mL) | Weight-based dosing | 50 - 60 | 62 | 66 | +6.4% |
| Cmax (ng/mL) | Weight-based dosing | 60 - 70 | 59.7 | 59.9 | +0.4% |
| Cmax (ng/mL) | Weight-based dosing | 70 - 80 | 57.6 | 57.1 | -0.9% |
| Cmax (ng/mL) | Weight-based dosing | 80 - 90 | 55.5 | 58.5 | +5.5% |
| AUC0-∞ (obs) (ng*h/mL) | 8 mg fixed dose | 30 - 40 | 3100 | 3150 | +1.7% |
| AUC0-∞ (obs) (ng*h/mL) | 8 mg fixed dose | 40 - 50 | 2470 | 2470 | +0.2% |
| AUC0-∞ (obs) (ng*h/mL) | 8 mg fixed dose | 50 - 60 | 2080 | 2080 | +0.0% |
| AUC0-∞ (obs) (ng*h/mL) | 8 mg fixed dose | 60 - 70 | 1910 | 2000 | +4.8% |
| AUC0-∞ (obs) (ng*h/mL) | 8 mg fixed dose | 70 - 80 | 1690 | 1660 | -2.0% |
| AUC0-∞ (obs) (ng*h/mL) | 8 mg fixed dose | 80 - 90 | 1550 | 1390 | -10.8% |
| AUC0-∞ (obs) (ng*h/mL) | Weight-based dosing | 30 - 40 | 2120 | 2060 | -2.8% |
| AUC0-∞ (obs) (ng*h/mL) | Weight-based dosing | 40 - 50 | 2130 | 2200 | +3.6% |
| AUC0-∞ (obs) (ng*h/mL) | Weight-based dosing | 50 - 60 | 2270 | 2190 | -3.7% |
| AUC0-∞ (obs) (ng*h/mL) | Weight-based dosing | 60 - 70 | 2180 | 2200 | +1.2% |
| AUC0-∞ (obs) (ng*h/mL) | Weight-based dosing | 70 - 80 | 2050 | 2340 | +14.4% |
| AUC0-∞ (obs) (ng*h/mL) | Weight-based dosing | 80 - 90 | 2140 | 2010 | -6.4% |
chk <- simulated |>
  inner_join(published, by = "group", suffix = c("_sim", "_pub")) |>
  mutate(
    cmax_pct = 100 * (cmax_sim - cmax_pub) / cmax_pub,
    auc_pct = 100 * (aucinf.obs_sim - aucinf.obs_pub) / aucinf.obs_pub
  )
stopifnot(
  # Structural: a mis-transcribed CL, V1, dose or unit shifts every band.
  abs(median(chk$cmax_pct)) < 10,
  abs(median(chk$auc_pct)) < 10,
  # Envelope across the 12 band x strategy cells (200 subjects each).
  quantile(abs(chk$cmax_pct), 0.9) < 20,
  quantile(abs(chk$auc_pct), 0.9) < 20
)
Why AUCinf is compared on the median. Under the
published model, AUCinf of an 8 mg dose is 8000 / (CL/F)
and CL/F is log-normal with omega = 0.625, so AUCinf is log-normal too:
its median is the typical-value AUC (1892 ng*h/mL at 65 kg) and its mean
is larger by exp(0.625^2 / 2) = 1.22. The “mean” column of
Table S2 (1907 in the 60-70 kg group, 1553 in the 80-90 kg group) sits
on the typical-value AUC, while its SD (1553 and 1236) and CV (77-87%)
match the log-normal SD. The simulated mean and median are shown side by
side here:
nca_strat |>
  group_by(regimen, band) |>
  filter(is.finite(aucinf.obs)) |>
  summarise(mean = mean(aucinf.obs), median = median(aucinf.obs),
            sd = sd(aucinf.obs), .groups = "drop") |>
  left_join(
    published |>
      tidyr::separate(group, c("regimen", "band"), sep = " \\| ") |>
      select(regimen, band, `Table S2` = aucinf.obs),
    by = c("regimen", "band")
  ) |>
  dplyr::rename("Strategy" = regimen, "Weight group (kg)" = band,
                "Simulated mean" = mean, "Simulated median" = median,
                "Simulated SD" = sd) |>
knitr::kable(digits = 0, caption = "Simulated AUCinf (ng*h/mL) against Table S2.")| Strategy | Weight group (kg) | Simulated mean | Simulated median | Simulated SD | Table S2 |
|---|---|---|---|---|---|
| 8 mg fixed dose | 30 - 40 | 3622 | 3151 | 2536 | 3099 |
| 8 mg fixed dose | 40 - 50 | 3167 | 2472 | 2158 | 2468 |
| 8 mg fixed dose | 50 - 60 | 2676 | 2083 | 1891 | 2083 |
| 8 mg fixed dose | 60 - 70 | 2584 | 1998 | 2448 | 1907 |
| 8 mg fixed dose | 70 - 80 | 2049 | 1657 | 1429 | 1690 |
| 8 mg fixed dose | 80 - 90 | 1794 | 1386 | 1254 | 1553 |
| Weight-based dosing | 30 - 40 | 2651 | 2060 | 2020 | 2119 |
| Weight-based dosing | 40 - 50 | 2629 | 2203 | 1793 | 2126 |
| Weight-based dosing | 50 - 60 | 2712 | 2185 | 2191 | 2269 |
| Weight-based dosing | 60 - 70 | 2571 | 2201 | 1785 | 2175 |
| Weight-based dosing | 70 - 80 | 2776 | 2345 | 2002 | 2049 |
| Weight-based dosing | 80 - 90 | 2561 | 2006 | 1698 | 2143 |
The published central values track the simulated medians; the simulated means run about 20% higher. Nothing in the model can reconcile a log-normal CL/F with a mean AUCinf equal to the typical value, so the most likely explanation is that the Table S2 central value is a median (or the typical-value AUC) labelled as a mean. The Cmax comparison needs no such caveat: Cmax is far less skewed (CV about 33%), and the simulated means match Table S3 (and the simulated SDs match its SDs).
Assumptions and deviations
-
Lag-time implementation. The MLXTRAN code sets the
absorption rate to zero while
t < Tlag, wheretis time since the start of the record. For the single dose of this study that is identical to delaying the dose by Tlag, which is how the model encodes it (alag(depot)). For repeated doses the MLXTRAN form would lag only the first dose; the packaged model lags every dose, which is the physiologically intended behaviour. - Age exponent. -0.422 from Results 3.2 is used rather than the -0.42 of Table 2; the three-decimal value reproduces the Results’ V1/F of 199 L at 18 years and 116 L at 65 years.
- Age reference. 44.2517 years from the MLXTRAN covariate block; the Table 2 legend rounds it to 44.3 years.
- Units. The model takes the dose in mg and returns ng/mL (the MLXTRAN model returns Ac/V1 with the dose in ug). Concentrations are capillary whole-blood concentrations from volumetric microsamples, not plasma.
- Censoring. Observations below the 1.5 ng/mL LLOQ were fitted with the Monolix censored likelihood. The packaged model returns uncensored predictions; apply the LLOQ downstream as needed.
- Table S2 AUCinf. See the note above: the central values of Table S2 are compared against the simulated medians, not means.
- Virtual cohort. Weight and age distributions of the trial cohort are truncated normals chosen by the maintainers to approximate the Table 1 medians, interquartile ranges and ranges; the individual data are not public.
-
Screened covariates not retained. Sex (significant
on V2/F but no GOF improvement), lean body weight, BMI, height,
infection intensity and co-infection are listed in
covariatesDataExcludedor omitted. - Errata. No correction notice was found on EuropePMC as of 2026-09-30.